- Browse Categories
- YQFH Drone
- DJI Drone
- Other Drone
- Drone Payloads
- Robot
- Pipeline Detection Instrument
- 3D Laser Scanner
- Industrial Measurement Devices
- Weather Station Series
- Optical Survey Instruments
- GNSS RTK & CORS System
- BDS System Products
- Visual Displacement Monitoring System
- UWB Indoor Positioning System
- Hydrology Products
- Others
- Spectrometer
- Wet Blast Machine
- SDI Soil Tester
- Pengjin Smart Flying Drone Patrol and Inspection System
- Supercomputing
- Module
- Viscometer
- Electric Hygro-thermograph
- Echo Sounder
- Processing Software
- Keson Measuring Tools
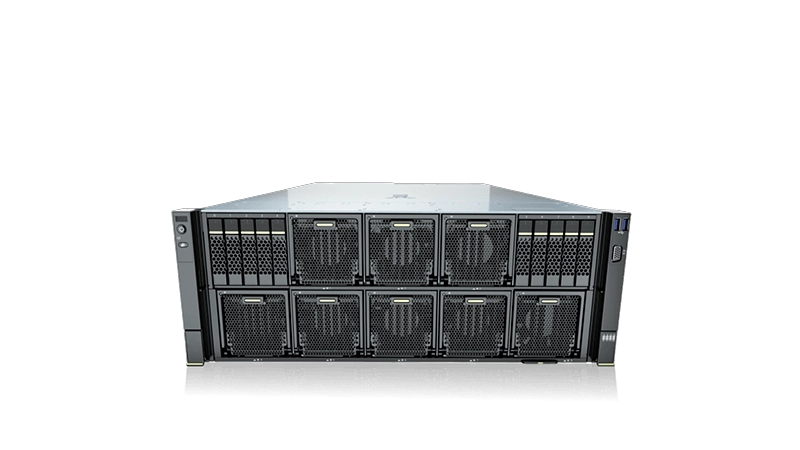
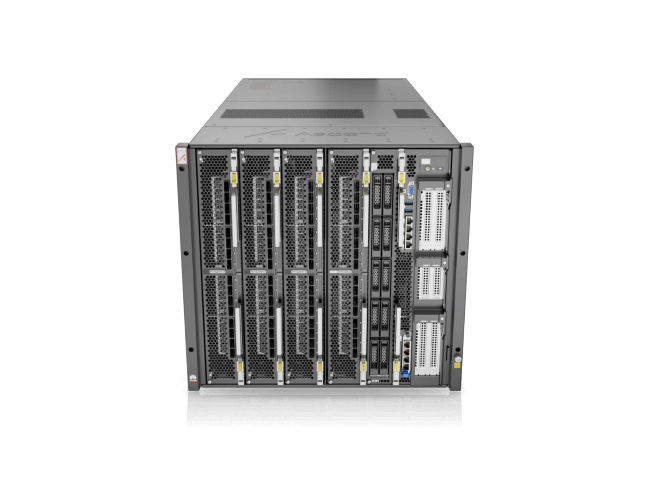
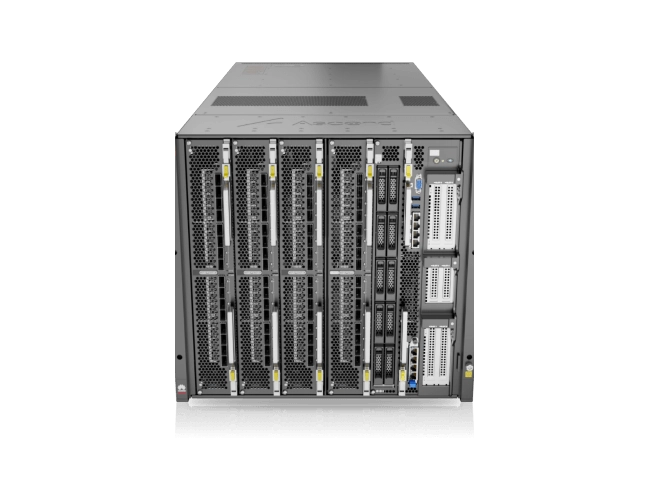
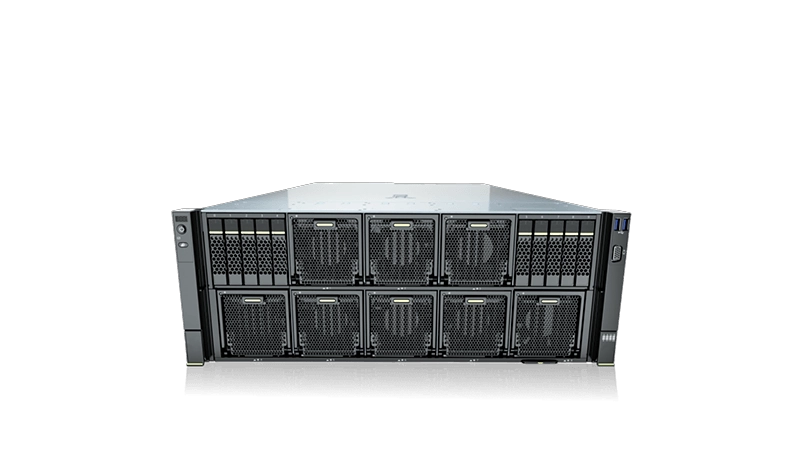
Atlas 800I A2 4U AI Inference Server
The Atlas 800I A2 inference server adopts an efficient 8-module inference approach, providing strong AI inference capabilities. It has advantages in computing power, memory bandwidth, and connectivity, and can be widely applied to generative large model inference, such as intelligent customer service, copywriting generation, knowledge accumulation, and other content generation scenarios. It supports NPU interconnection to improve large model inference efficiency.
1. Features
1.1 Core Hardware Configuration
• Processors and Acceleration Cards:
• CPU: Equipped with 4 Kunpeng 920 processors (supporting 48/64 cores, with clock speeds of 2.6/3.0 GHz).
• NPU (AI Processor): Based on the Huawei Ascend 910 AI processor, featuring an integrated HCCS NPU module.
• Memory Capacity: 64 GB per accelerator, totaling 512 GB of accelerator memory (HBM type); system memory supports up to 32 DDR4 DIMM slots.
• Bandwidth and Bus:
• Accelerator memory bandwidth: 800 GB/s (per NPU).
• Accelerator interconnect bandwidth: up to 392 GB/s (or 512 GB/s via PCIe 4.0 x16 NPU-CPU interconnect).
• Supported Data Types: FP32, FP16, and INT8.
1.2 System and Cooling
• Form Factor and Weight: 4U full-depth rack-mounted unit; dimensions: 175 × 447 × 790 mm (H x W x D); weight: approximately 90 kg.
• Cooling Design: Front-to-rear air cooling, featuring 8 hot-swappable fan modules with N+1 redundancy.
• Maximum System Power Consumption: 10.4 kW.
1.3 Software Ecosystem
• Software Stack: Fully compatible with Huawei CANN, MindSpore, MindIE, AscendCL, and the PyTorch Adapter for Ascend; supports mainstream inference frameworks such as vLLM, vLLM-Ascend, and MindIE Turbo.
• Virtualization Capabilities: Supports Huawei vNPU compute resource partitioning, device passthrough, and containerized deployment via the Ascend software stack. Typical Application Scenarios
• Enterprise-grade Large Language Model (LLM) inference, generative AI services, Retrieval-Augmented Generation (RAG), intelligent customer service, content generation, knowledge processing, and high-throughput AI inference services.
2. Technical specifications
| Products | Atlas 800I A2 inference server |
| Form | 4U AI servers |
| CPU | 4 * Kunpeng 920 |
| Memory | 32 DDR4 memory slots, up to 3200 MT/s , and single memory stick supports 16/32/64 GB capacity |
| Local storage | 8 * 2.5 SATA+2 * 2.5 NVMe 4 * 2.5 SATA+6 * 2.5 NVMe |
| RAID support | Supports RAID 0/1/10/5/50/6/60 |
| Internal network | An optional NPU fully interconnected model with a total connectivity bandwidth of 392GB/s |
| External networks | 8 * 200GE QSFP interfaces with direct output, RoCE protocol |
| PCIe interface | Supports up to 3 PCIe 4.0 expansion slots |
| Power supply | Four hot-swappable 2.6kW power modules, supporting 2+2 redundancy |
| Power supply | 200 ~ 240V AC 240V DC |
| Cooling method | Wind cooling |
| Fan | Supports 8 hot-swappable fan modules and N+1 redundancy |
| Operating environment temperature | 5℃~35℃(41℉~95℉) |
| Structural dimensions | 175mm (height) * 447mm (width) * 790mm (depth) |
- Other Products